Data platform and nightly automation pipeline
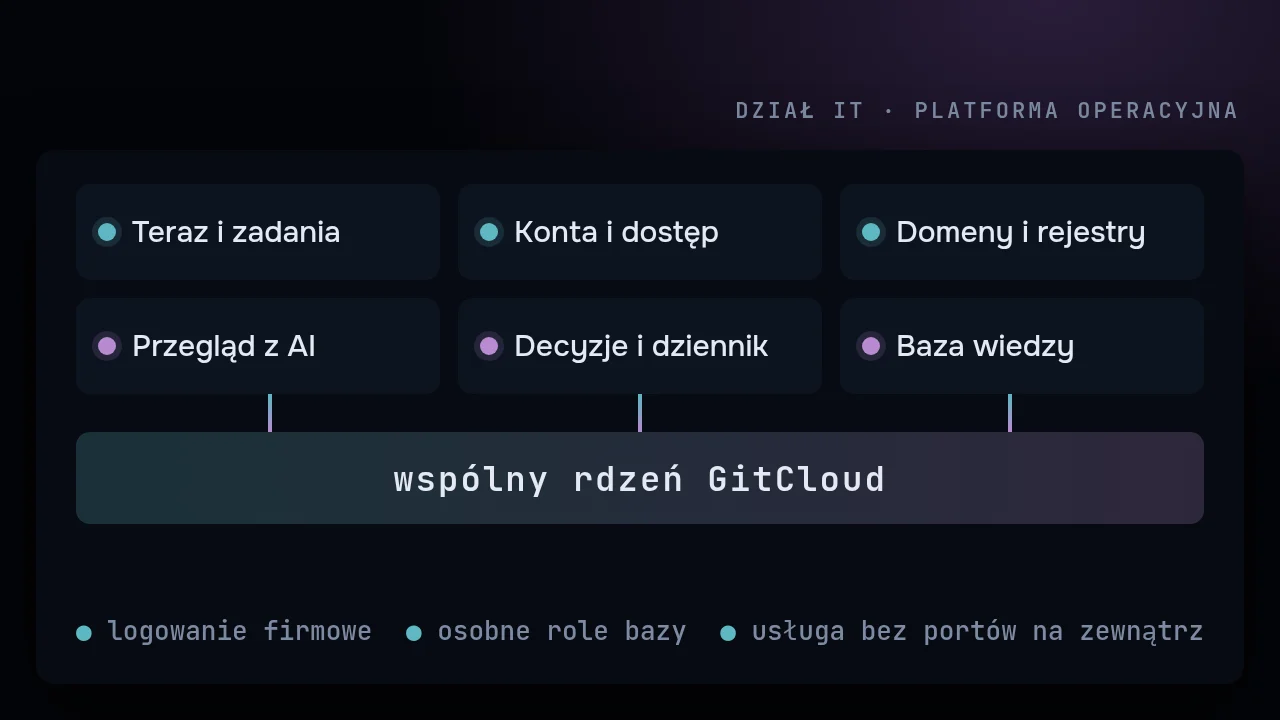
One database for the whole system, a schedule described in code and a night after which, at 7:00, everything is backed up, checked and gathered in one summary.

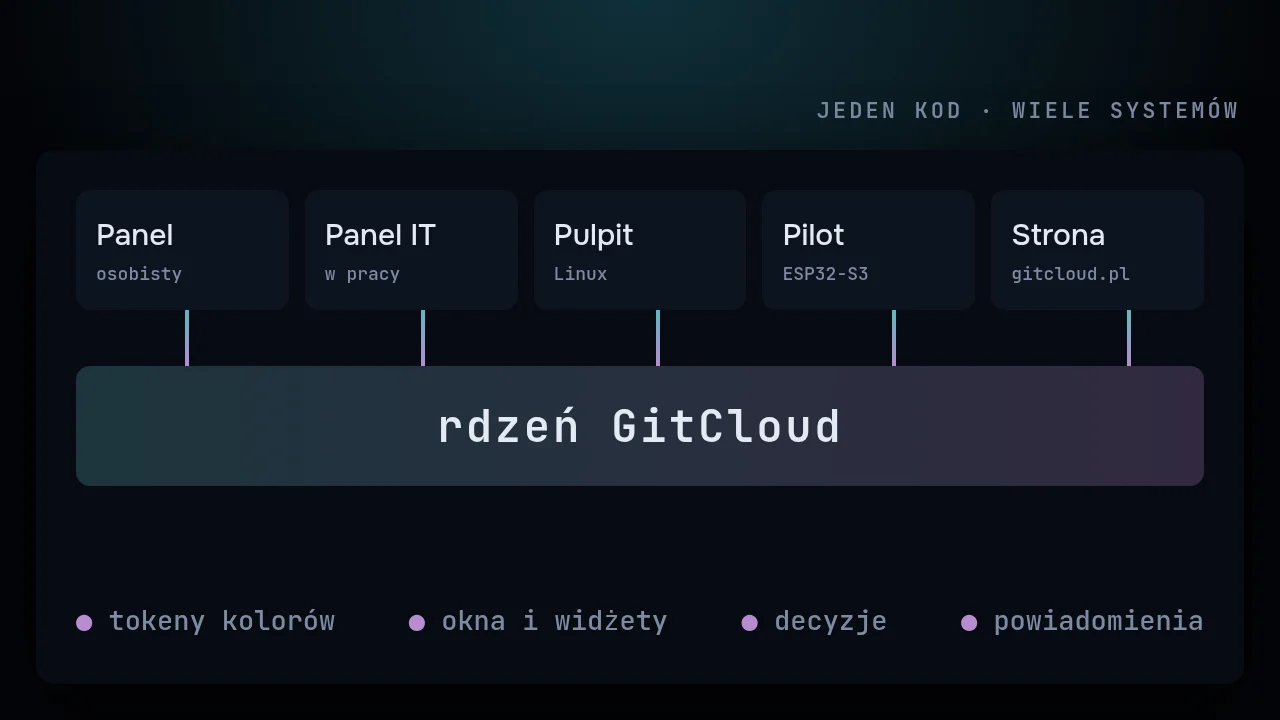
Diagrams drawn from the schedule and the report, without addresses or internal names.
Task
Dozens of scripts wrote data to files and separate databases, jobs ran scattered throughout the day, and reports trickled in until noon. Backups existed, but nobody checked whether they could be restored.
Solution
A shared database with separate access for each service and schema changes in the repository. The schedule is described in code and compared with the server to catch manual changes. The router, virtualisation and the server OS are in code too (Terraform, Ansible) and compared nightly with what is running. The night has a fixed order: backups, a restore test, a maintenance window with a check after every step, code review, reports and one summary in the morning. Backups go to three places.
Result
- Every night a restore test of random files and the database, the whole backup checked within a week
- On Sunday a full restore drill in isolation
- Backups in three places, database archive with point-in-time recovery
- Night maintenance without manual confirmation, the first error stops the rest
- On Sunday the jobs container is built from scratch from code in isolation, the first time in 5 minutes
My role
Architecture, database schema and migrations, scheduling, backups and their verification.